The Essential Guide to Data Engineering in Modern Businesses

Bad data rarely announces itself. It shows up as a late finance report, a customer dashboard no one trusts, a stock forecast that misses demand, or an AI project that never leaves the pilot stage.
Modern businesses collect data from websites, payment tools, mobile apps, warehouses, sensors, call centres, suppliers, and third-party platforms. That data has value only when it can be found, trusted, joined, secured, and used at the right time. This is where data engineering earns its place.
Data engineering is the work of building and maintaining the systems that move data from where it is created to where it can be used. It sits between raw data and useful decisions. Without it, analytics becomes slow, reporting becomes fragile, and machine learning becomes guesswork.

What data engineering means in practice
At its simplest, data engineering turns raw data into usable data. That sounds neat, but the work covers many moving parts.
A data engineer may build a pipeline that copies sales data from an online shop into a warehouse every hour. They may clean customer records so the same person does not appear five times with slightly different names. They may set up checks so a report does not load if half the rows are missing. They may also control who can access sensitive fields such as payment details or health information.
The goal is not just to move data. The goal is to make data reliable, timely, traceable, and safe.
A solid data engineering setup usually includes:
Sources that create or store data, such as apps, databases, machines, and external services
Data pipelines that collect, transform, and load information
Storage systems such as data warehouses, data lakes, or lakehouses
Quality checks that catch missing, duplicated, or strange records
Models that shape data for reporting, analytics, and AI
Access controls, audit trails, and privacy safeguards
Monitoring that alerts teams when something breaks
This work is often invisible when it goes well. That is part of the challenge. People notice the dashboard, the forecast, or the product recommendation. They do not always notice the system underneath that makes those outputs possible.
Yet without Data Engineering, those outputs are often built on weak foundations.
Why data engineering matters more than ever
Many organisations now treat data as a shared business asset. Sales teams use it to understand buying patterns. Operations teams use it to plan stock and staffing. Finance teams use it for forecasts. Product teams use it to spot friction. Leadership teams use it to track performance across regions.
The problem is that business data often starts life in separate systems. A retailer might have ecommerce data in one place, in-store sales in another, loyalty records in another, and supplier data somewhere else. Each system may use different names, formats, and update times.
Data engineering brings those pieces together.
The value of data grows when people can trust it, find it, and use it without rebuilding the same work again and again.
Good data engineering helps businesses in several practical ways.
It reduces manual reporting. Teams spend less time copying CSV files, fixing spreadsheet errors, and asking which version is correct.
It improves decision speed. Leaders can use fresh information rather than waiting days for reports to be prepared.
It supports better customer experiences. Clean, connected data helps businesses understand orders, preferences, support history, and service issues.
It makes AI and machine learning more useful. Models need consistent, well-labelled, relevant data. Poor input creates poor output.
It lowers risk. Clear ownership, access controls, and audit records help businesses handle sensitive information with care.

Consider a logistics company. Delivery times, route data, fuel use, vehicle maintenance, warehouse scans, and customer notifications may all sit in separate tools. With sound data engineering, this information can feed a shared system. The company can spot repeated delays, compare route performance, plan maintenance earlier, and give customers clearer updates.
The same pattern applies across sectors. In healthcare, data engineering can help join appointment, staffing, and equipment data while protecting patient privacy. In manufacturing, it can connect machine readings with quality checks. In financial services, it can support fraud monitoring and regulatory reporting. In public services, it can help teams allocate resources based on clearer demand signals.
The details vary, but the need is similar. Data must move from scattered systems into a trusted form that people and tools can use.
The core components of a modern data platform
A data platform is the set of tools, rules, and processes that support data work across a business. It does not need to be complex from day one. In fact, many strong platforms start with a few clear choices and grow as needs become more advanced.
The main components are easier to understand when viewed as a flow.
Component | What it does | Common business use |
Data sources | Create or hold raw information | Sales systems, apps, sensors, finance tools |
Ingestion | Brings data into the platform | Scheduled imports, event streams, API connections |
Storage | Keeps data in a central place | Warehouses, lakes, lakehouses |
Transformation | Cleans and shapes data | Standard names, joined tables, business metrics |
Quality checks | Tests data before use | Missing values, duplicate records, late files |
Access control | Manages who can see what | Role-based permissions, masked sensitive fields |
Monitoring | Tracks pipeline health | Alerts, logs, failed job reports |
Serving layer | Makes data available | Dashboards, reports, data products, AI models |
These components can run on cloud services, on-premise systems, or a mix of both. The right choice depends on cost, existing systems, regulation, skills, and the pace at which data changes.
A data warehouse is often used for structured reporting and analytics. It is good for well-defined data such as sales, orders, and finance records.
A data lake stores a wider range of raw or semi-structured data, such as logs, documents, images, and sensor files. It can be useful when a business wants flexibility, but it needs discipline to avoid becoming a dumping ground.
A lakehouse aims to bring parts of both worlds together. It can store varied data while supporting analysis in a more managed way.
The technology matters, but the operating model matters more. A business can buy expensive tools and still fail if no one owns definitions, quality, access, or maintenance.
What data engineers actually do
Data engineers build systems, but they also make design choices that affect how people across the business use information.
A typical data engineering role may include writing code, designing data models, working with cloud tools, managing pipeline schedules, handling permissions, and responding to failures. The role often connects software engineering, database design, analytics, security, and operations.
A good data engineer asks practical questions.
Where does the data come from? How often does it change? What does each field mean? Who owns it? Who is allowed to see it? What happens if the source system sends a blank file? How will teams know if a pipeline fails? Can the system handle more data next year?
These questions sound basic, but they prevent expensive problems.
For example, a finance team may define “monthly revenue” one way, while a sales team defines it another way. One includes refunds, one does not. One records revenue when an order is placed, another when payment clears. Without clear data modelling, both teams may produce different numbers and each may believe theirs is right.
Data engineers help turn such definitions into shared data models. A shared model does not remove every debate, but it gives teams a common base.

Their work also protects time. If every analyst builds their own version of customer, product, order, and location tables, effort gets repeated and errors spread. A well-built data layer gives teams reusable building blocks.
Strong data engineering also builds trust by making data lineage visible. Lineage shows where a data point came from, what changed along the way, and where it is used. When a number looks wrong, lineage helps teams trace the issue quickly.
Common mistakes businesses make with data engineering
Many data problems do not start with bad intent. They start with shortcuts that work for a while, then break under pressure.
One common mistake is treating data engineering as a one-off project. A business builds a warehouse, connects a few sources, and assumes the work is done. But systems change, products change, regulations change, and users ask new questions. Data platforms need ongoing care.
Another mistake is building pipelines without ownership. If no one owns a source system, no one warns the data team before a field changes or an API stops working. A small change can break reports across the business.
Businesses also run into trouble when they collect everything without purpose. More data is not always better. Storing large amounts of unused information adds cost, risk, and complexity. Clear use cases help teams decide what to collect, how long to keep it, and who should access it.
Poor documentation is another common issue. A table called `customer_status` may look simple, but does it mean active, paying, registered, verified, or recently engaged? If the definition lives only in someone’s memory, the business has a fragile system.
Security can also be bolted on too late. Access rules should be part of the design, not an afterthought. Sensitive data should be identified early, protected properly, and shared only with people who need it for valid work.
A final mistake is chasing tools before fixing basics. New platforms can help, but they cannot replace clear data definitions, sensible ownership, and regular quality checks.
Good data engineering is partly technical and partly organisational. The best systems reflect how the business works, not just how the technology works.
How to build a stronger data engineering foundation
A business does not need to rebuild everything at once. Progress often comes from making a few disciplined choices and improving them over time.
Start with the most important decisions the business needs to make. These might involve revenue, customer retention, stock availability, risk, or operational performance. Then work backwards to the data needed to support those decisions.
Next, identify key data sources and owners. Each important dataset should have someone responsible for its meaning and quality. This person may not be a data engineer. They may sit in finance, operations, product, or customer service.
Set clear definitions for your core measures. Terms such as customer, order, churn, margin, and active user should mean the same thing across reports where possible. When different definitions are needed, label them clearly.
Build pipelines with checks from the beginning. Useful checks might include:
A file arrives on time
A table has the expected number of rows
Required fields are not blank
Values fall within sensible ranges
Duplicate records stay below an accepted level
Sensitive fields are masked or restricted
Use monitoring so failures do not sit hidden. A quiet failure can be worse than a loud one, because teams may keep making decisions from stale or incomplete data.
Document the parts people rely on. Documentation does not need to be perfect, but it should explain what key tables contain, how measures are calculated, and who to contact when something looks wrong.
Plan for change. Source systems will change formats. Teams will request new metrics. Data volume may grow. Regulations may shift. Build with enough flexibility to adapt without rebuilding from scratch each time.
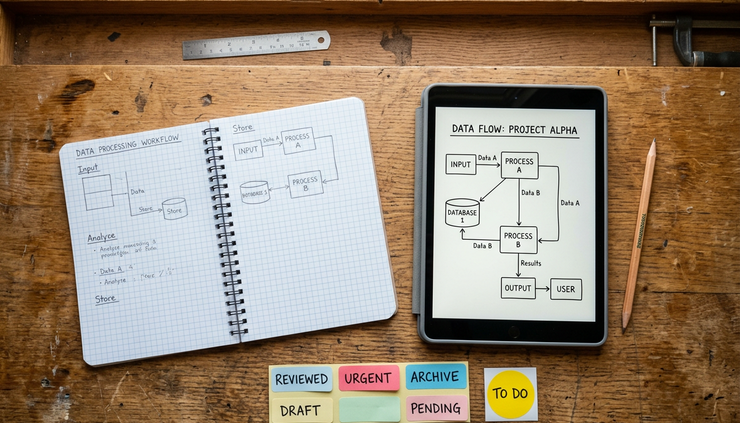
Above all, treat data engineering as a shared business capability. Engineers can build the platform, but useful data needs input from the people who understand the processes behind it. A stock record, claim status, support category, or payment event carries business meaning. That meaning cannot be guessed from code alone.
The takeaway for modern businesses
Data engineering is no longer a background technical concern. It shapes whether a business can trust its reports, improve operations, serve customers well, and use AI with confidence.
The essential point is simple. Data creates value when it moves through well-designed systems with clear ownership, strong quality checks, and sensible access controls. Tools help, but the real advantage comes from combining technical skill with business understanding.
For any organisation looking to improve its use of data, the next step is practical. Pick one high-value decision or process, trace the data that supports it, and look for weak points. Fix the sources, definitions, pipelines, and checks that matter most.
That focused work builds the foundation for everything that follows.


Comments